Setting Up a Databricks Custom Notebook
Custom Ingestion, Custom Parse, and Custom Post Output can run your own Databricks notebooks. Set the notebook path on the Source or Output, and DataForge runs it through Sparky on your processing compute, reporting status, timeouts, and errors on the DataForge process.
Changed in 11.0
Before 11.0, each custom step needed its own Compute Configuration with Job Task Type set to Custom Notebook, and that configuration held the notebook path. The 11.0 upgrade moves existing notebook paths and parameters onto the Source or Output and converts custom notebook compute into standard compute assigned through Process Configurations. See DataForge 11.0 Breaking Changes and Upgrade Preparation.
Finding the Notebook Path
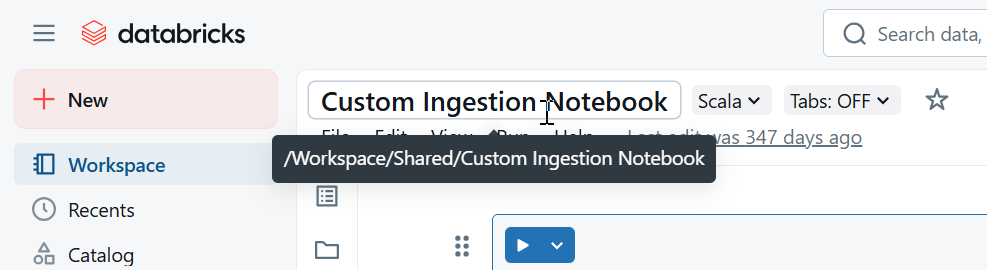
In the Databricks UI, open the notebook and hover over its name to reveal the full path. Copy it, including the leading slash.
Notebook Path and Repository Path
Every custom step has two path settings:
- Notebook Path (required): the notebook to run. Enter a fully qualified path, or a path relative to the Repository Path.
- Repository Path (optional): a folder that prefixes the Notebook Path. DataForge joins the two with a single
/, so leading and trailing slashes do not matter. When Repository Path is empty, the Notebook Path is used as entered.
Repository Path lets each Project run its own copy of a notebook. Add a Repository Path Project Variable, and import replaces the folder with the target Project's value while keeping the Notebook Path. For example, a production Project can use /Workspace/datalake/dataforge-sdk/Loopback while a developer's Project uses the same notebook from their own Git folder, /Workspace/Users/<user>/datalake/dataforge-sdk/Loopback. Both use the Notebook Path Post-Process Daily Snapshot.
Custom Ingestion
- Open the Source Settings page for the Source, or create a new Source.
- Set Connection Type to Custom.
- Enter the Notebook Path, and optionally the Repository Path.
- Optionally select a Custom Connection to pass encrypted parameters to the notebook.
- Click Save.
Test with Pull Now or by setting a schedule.
Custom Parse
- Open the Source Settings page for the Source, or create a new Source.
- Set Connection Type to File. Custom parse only runs for file sources.
- Set Parser to Custom.
- Enter the Notebook Path, and optionally the Repository Path.
- Click Save.
Test with Pull Now or by resetting parse for an input.
Custom Post Output
- Open the Output Settings page for the Output, or create a new Output.
- Set Post Output Commands to Custom Notebook.
- Enter the Notebook Path, and optionally the Repository Path.
- Click Save.
The notebook runs after each output process. Test with Reset Output on the Mapping page or by resetting a specific channel. To read credentials, create a Custom Connection with Direction set to Output and read it by name in the notebook.
Compute and Libraries
Custom notebooks run on the default Compute Configuration. To run a custom step on different compute, such as a larger cluster or one with extra libraries, add a process override for that custom process type in the Source's Process Configuration. Add libraries beyond the DataForge SDK to that Compute Configuration under Parameters > Job Configuration > Libraries.
See Compute Configuration for Custom Processing Steps for details.